
Provide Valid NS0-593 Dumps To Help You Prepare For NetApp Certified Support Engineer ONTAP Specialist Exam Jun 28, 2024
Network Appliance NS0-593 Dumps Questions [2024] Pass for NS0-593 Exam
NEW QUESTION # 18
You recently discovered the error message shown below in your ONTAP logs.
What should be your first action to correct this Issue?
- A. Determine the root cause behind the inconsistency before attempting any recovery procedure.
- B. Use the wafliron command against my_data_vol to solve the inconsistency on the volume.
- C. Use the storage takeover command on the storage controller that contains my_data_vol.
- D. Power cycle all the disk storage shelves that contain drives of the aggregate with the my_data_vol
volume.
Answer: D
NEW QUESTION # 19
You created a new NetApp ONTAP FlexGroup volume spanning six nodes and 12 aggregates with a total size of 4 TB. You added millions of files to the FlexGroup volume with a flat directory structure totaling 2 TB, and you receive an out of apace error message on your host.
What would cause this error?
- A. The maxdirsize Is exceeded in the ONTAP software.
- B. The maximum number of volume constituents has been reached in the ONTAP software.
- C. All constituent volumes are full.
- D. The inode limit is exceeded in the ONTAP software.
Answer: A
Explanation:
The maxdirsize is the maximum size of a directory in a FlexVol or FlexGroup volume. It is determined by the number of inodes allocated to the directory. If the directory contains more files than the maxdirsize can accommodate, then the ONTAP software will return an out of space error message to the host, even if the volume has enough free space. This can happen when a FlexGroup volume has a flat directory structure with millions of files, as the maxdirsize is not automatically adjusted for FlexGroup volumes12. Reference: 1: FlexGroup volumes: Frequently asked questions | NetApp Documentation 2: How to increase the maxdirsize of a FlexVol volume - NetApp Knowledge Base
NEW QUESTION # 20 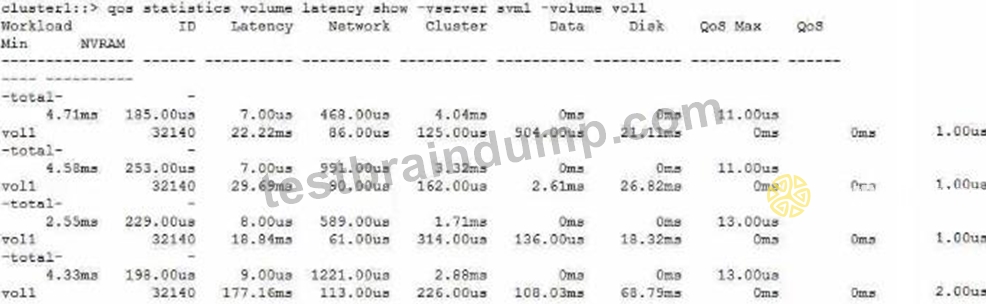
Referring to the exhibit, from which delay center is most of the latency for voll?
- A. NVRAM
- B. Network
- C. Disk
- D. Data
Answer: B
NEW QUESTION # 21
You have a 4-node NetApp ONTAP 9.8 cluster with an AFF A400 HA pair and a FAS8300 HA pair with 16
TB NL-SAS drives. You are asked to automatically tier 150 TB of Snapshot copy data from the AFF A400
aggregates to the FAS8300.
In this scenario, which ONTAP license must be added to the cluster to accomplish this task?
- A. FabricPool license
- B. S3 license
- C. TPM license
- D. VE license
Answer: C
NEW QUESTION # 22
Your customer calls you because one application is not able to access a NetApp ONTAP S3 bucket. While reviewing the EMS log on the cluster, you see the following message:
The same credentials work in another application.
In this scenario, what would cause this problem?
- A. The application is using v4 signatures.
- B. The application is trying to access using the HTTP protocol.
- C. The application is trying to log in as an anonymous user.
- D. The application is using v2 signatures.
Answer: D
Explanation:
The error message indicates that the access is denied for user 'anonymous user' (Vserver 50), from client IP 10.10.10.10 accessing resource '/offload-target'. This means that the application is not providing a valid user name or access key to authenticate with the ONTAP S3 server. According to the NetApp documentation1, ONTAP S3 server supports both v2 and v4 signatures, but v2 signatures are deprecated and not recommended. Therefore, the application should use v4 signatures to access the ONTAP S3 bucket. Additionally, the application should specify the bucket name in the host name, not in the resource path, as shown in the following example2:
https://bucket-name.s3-server-name.com/object-name
Reference = 1 ONTAP S3 Server Overview - NetApp Documentation 2 Accessing an ONTAP S3 bucket - NetApp Documentation
NEW QUESTION # 23
You are troubleshooting a CIFS connection issue that is reported by some users. You decide to collect a packet
trace.
In this scenario, after you generate the packet trace, where do you find the trace file?
- A. /packet_traces of the node hosting the LIF
- B. /etc/log/packet_traces of the node hosting the LIF
- C. /vol0/paclcet_traces of the CIFS SVM
- D. /etc/log/mlog/packet._traces Of all nodes
Answer: D
NEW QUESTION # 24
A user reports that a colleague saved a file called Test.txt from a UNIX system to a multiprotocol volume. When opening the file later from a Windows system, it was not the file that they wanted. The file that they wanted was named TEST~1.TXT.
Which statement explains this behavior?
- A. Windows Volume Shadow Copy Service stored an older version of the file.
- B. A Snapshot copy preserved two versions of the file.
- C. UNIX name mapping updated the filename.
- D. Case Insensitivity of SMB clients caused the file to be displayed with a different name.
Answer: D
Explanation:
= The multiprotocol volume allows clients to access files using both NFS and SMB protocols. The NFS protocol is case-sensitive, meaning that Test.txt and TEST~1.TXT are two different files. The SMB protocol is case-insensitive, meaning that it treats uppercase and lowercase letters as the same when searching for a file. Therefore, when the user opened the file from a Windows system using SMB, the system could not distinguish between Test.txt and TEST~1.TXT and displayed one of them arbitrarily. This could lead to confusion and data loss if the user modified or deleted the wrong file. Reference = Client protocols; Multiprotocol NAS in NetApp ONTAP Overview and Best Practices, page 30-31.
NEW QUESTION # 25
A customer wants to connect a NetApp AFF A700 system to a 40GbE switch. The controllers have a 10/40G
Ethernet card in slot 4 for this purpose. The link comes up fine on node 2,but it will not come up on node 1.
You look at the AutoSupport data for the nodes in question and see the output shown in the exhibit.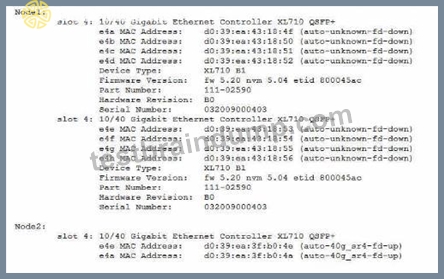
What is the cause of the customer's problem?
- A. The ports are configured for 4x10Gbit instead of 40Gbit.
- B. The cable is plugged in upside down.
- C. The incorrect cable is used.
- D. The port has an incorrect SFP inserted.
Answer: A
NEW QUESTION # 26
A customer's storage administrator Informs you about the deactivated Automatic Switchover (AUSO) feature
on their MetroCluster IP environment.
What Information would you tell your customer in this scenario?
- A. The AUSO feature cannot be activated due to a non-mirrored aggregate.
- B. A faulty link automatically deactivated the AUSO feature.
- C. The AUSO feature is not available in Metrocluster IP installations by design.
- D. This is a configuration failure, you can activate that feature for the customer.
Answer: A
NEW QUESTION # 27
You notice poor performance on your FlexGroup and execute the system node run -node * flexgroup show command for more Information. You notice the "Urge" column has non-zero values.
In this scenario, which statement is true?
- A. The constituent volumes are completely full.
- B. The aggregate is completely full.
- C. The constituent volumes are out of Inodes.
- D. The data placement is uneven.
Answer: D
Explanation:
= The "Urge" column in the flexgroup show command indicates the urgency of data rebalancing for each constituent volume. A non-zero value means that the data placement is uneven across the volumes, which can affect the performance of the FlexGroup. The target value is the desired percentage of data for each volume, and the difference value is the deviation from the target. The FlexGroup tries to balance the data placement by moving data between the volumes, but this process can be slow or interrupted by other factors. Therefore, it is recommended to monitor the "Urge" column and take corrective actions if the values are high or persistent. Reference = What do "flexgroup show" target and urgency and other columns mean?, NetApp ONTAP FlexGroup volumes - Best practices and implementation guide
NEW QUESTION # 28
You receive the "Unable to connect to the management gateway server"error when trying to connect to a node
management IP.
In this situation, how do you determine whether core dumps are generated for the mgwd user space process?
- A. Log in to the service processor and collect the core dumps from the service processor.
- B. Log in to the nodeshell using the node console and collect the core dumps from the nodeshell.
- C. Log in to the systemshell and collect core dumps from thesystemshell.
- D. Log in to the clustershell using the node console and collect the core dumps from the clustershell.
Answer: A
NEW QUESTION # 29
Your customer added a new DS4246 shelf to their FAS2750 single-node system and created a new aggregate
on the new shelf. Two weeks later, they log into Active IQ and discover the Medium Impact error shown
below.
Shelves with both connections via the same SAS path detected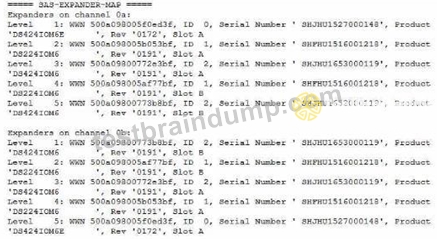
Referring to the exhibit, which statement is correct?
- A. This situation is normal for a FA57750 single-node system.
- B. Active IQ Is not aware of the shelf configuration for a single-node system.
- C. In a FAS2750 system, the internal shelf is only seen on one path, and the external shelves are seen on
two paths. - D. The cables are cabled Incorrectly on the SAS stack.
Answer: A
NEW QUESTION # 30 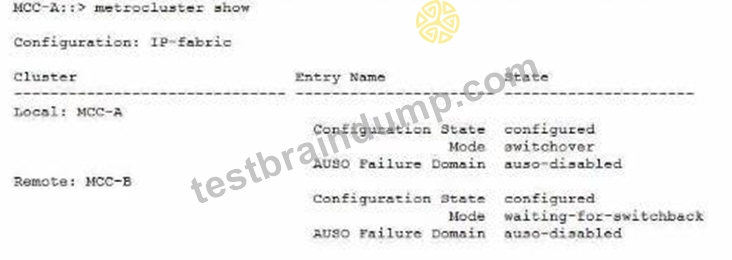
Referring to the exhibit, what do you need to do to return the MetroCluster to a normal state?
- A. Enter the metrocluster switchback command on Site A.
- B. Enter the storage failover giveback command on Site A.
- C. Enter the metroclustor switchback command on Site B.
- D. Enter the storage failover giveback command on Site B.
Answer: A
NEW QUESTION # 31
A customer enabled NFSv4.0 on an SVM and changed the client mount from NFSv3 to NFSv4. Afterwards, the customer found that the directory owner was changed from root to nobody.
In this scenario, which statement is true?
- A. The ID mapping domains do not match between the client and server.
- B. The clients must be restarted to start using NFSv4.
- C. The customer did not configure name services on the SVM.
- D. The export policy is not configured properly.
Answer: A
Explanation:
NFSv4 is a network file system protocol that supports security, performance, and scalability features. NFSv4 uses ID mapping to ensure that the permissions of files and directories are consistent across different NFSv4 servers and clients1 ID mapping is the process of translating the user and group identifiers (UIDs and GIDs) of the local system to the user and group names (user@domain and group@domain) of the remote system, and vice versa. ID mapping is done by the idmapd service, which uses the /etc/idmapd.conf file to determine the domain name of the system2 ID mapping requires that the NFSv4 server and client have the same domain name configured in the /etc/idmapd.conf file. If the domain names do not match, the idmapd service cannot map the UIDs and GIDs to the user and group names, and the permissions of the files and directories will be shown as nobody:nobody, which is the default anonymous user3 Therefore, if a customer enabled NFSv4.0 on an SVM and changed the client mount from NFSv3 to NFSv4, and found that the directory owner was changed from root to nobody, the most likely cause is that the ID mapping domains do not match between the client and server. The customer should check and correct the /etc/idmapd.conf file on both systems, and restart the idmapd service and remount the NFSv4 share4 Reference:
1: ONTAP 9 - Network File System (NFS) - The Open Group 2: ONTAP 9 - NFSv4 and NFSv4.1 Enhancements - The Open Group 3: NFSv4 mount incorrectly shows all files with ownership as nobody:nobody - Red Hat Customer Portal 4: NFSv4 mountpoint shows incorrect ownerships as nobody:nobody in CentOS/RHEL - The Geek Diary
NEW QUESTION # 32
Your customer has deployed a two petabyte NetAppONTAP FlexGroup volume across their 4-node ONIAP
9.8 cluster. They plan to store over three billion files. They want to prevent file 10 conflicts since files are
placed into the FlexGroup volume.
In this scenario, which two NFS SVM parameters should be enabled? (Choose two.)
- A. -v3-64bit-identifiers
- B. -v4-fsid-change
- C. -v4-64bit-idantifiers
- D. -v3-fsid-change
Answer: A,D
NEW QUESTION # 33
You notice poor performance on your FlexGroup and execute the system node run -node * flexgroup show command for more Information. You notice the "Urge" column has non-zero values.
In this scenario, which statement is true?
- A. The constituent volumes are completely full.
- B. The aggregate is completely full.
- C. The constituent volumes are out of Inodes.
- D. The data placement is uneven.
Answer: D
Explanation:
= The "Urge" column in the flexgroup show command indicates the urgency of data rebalancing for each constituent volume. A non-zero value means that the data placement is uneven across the volumes, which can affect the performance of the FlexGroup. The target value is the desired percentage of data for each volume, and the difference value is the deviation from the target. The FlexGroup tries to balance the data placement by moving data between the volumes, but this process can be slow or interrupted by other factors. Therefore, it is recommended to monitor the "Urge" column and take corrective actions if the values are high or persistent. Reference = What do "flexgroup show" target and urgency and other columns mean?, NetApp ONTAP FlexGroup volumes - Best practices and implementation guide
NEW QUESTION # 34
You have a 2-node NetApp FAS2750 switchless cluster with twenty-four 1.8 TB disks that is experiencing performance issues. Upon investigation, you discover several type B consistency points.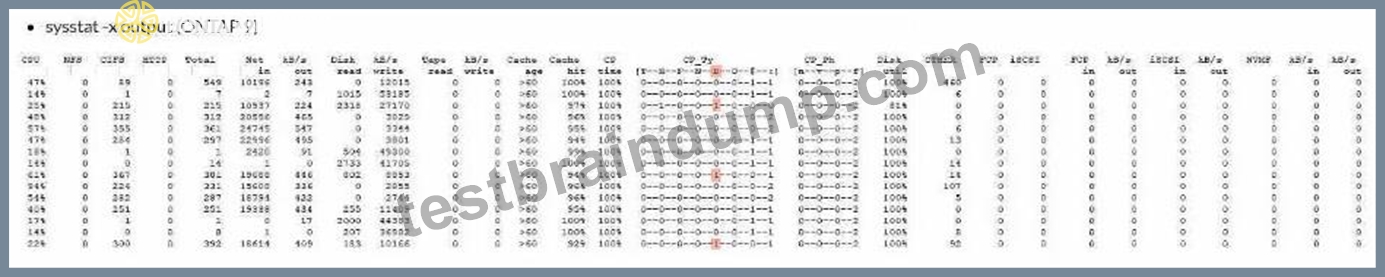
Referring to the exhibit, which corrective action would address these consistency points?
- A. Convert the 2-node switchless cluster to a 2-node switched cluster.
- B. Add an additional shelf of twenty-four 1.8 TB disks.
- C. Replace the twenty-four 1.8 TB disks with twelve 4 TB disks.
- D. Create additional data LIFs.
Answer: B
Explanation:
A type B consistency point (CP) is triggered when the NVRAM buffer is full and needs to be flushed to disk. A type B CP indicates that the write workload is higher than the disk throughput, and the system is experiencing back pressure1 A switchless cluster is a cluster configuration that does not use external switches for cluster interconnect and management network. A switchless cluster has lower bandwidth and redundancy than a switched cluster, and is limited to two nodes2 The exhibit shows the output of the sysstat -x command, which displays the system performance statistics in extended mode. The output shows that the system has high CPU utilization, high disk utilization, high NVRAM utilization, and several type B CPs. These are signs of performance issues and resource contention3 The best corrective action to address these consistency points is to add an additional shelf of twenty-four 1.8 TB disks. This will increase the disk capacity and throughput, and reduce the disk utilization and the frequency of type B CPs4 Creating additional data LIFs will not address the consistency points, because the data LIFs are used for data access protocols, not for NVRAM flushing5 Converting the 2-node switchless cluster to a 2-node switched cluster will not address the consistency points, because the cluster interconnect and management network are not related to the disk performance6 Replacing the twenty-four 1.8 TB disks with twelve 4 TB disks will not address the consistency points, because the disk throughput will not increase, and the disk utilization will remain high7 Reference:
1: Where can I learn more about Consistency Points? - NetApp Knowledge Base 2: ONTAP 9 - Cluster and SVM Peering Express Guide - The Open Group 3: ONTAP 9 - Commands: Manual Page Reference - The Open Group 4: ONTAP 9 - Hardware Universe - The Open Group 5: ONTAP 9 - Network Management Guide - The Open Group 6: ONTAP 9 - Clustered Data ONTAP Concepts Guide - The Open Group 7: ONTAP 9 - Logical Storage Management Guide - The Open Group
NEW QUESTION # 35
A user reports that a colleague saved a file called Test.txt from a UNIX system to a multiprotocol volume.
When opening the file later from a Windows system, it was not the file that they wanted. The file that they
wanted was named TEST~1.TXT.
Which statement explains this behavior?
- A. Windows Volume Shadow Copy Service stored an older version of the file.
- B. UNIX name mapping updated the filename.
- C. A Snapshot copy preserved two versions of the file.
- D. Case Insensitivity of SMB clients caused the file to be displayed with a different name.
Answer: C
NEW QUESTION # 36
When you review performance data for a NetApp ONTAP cluster node, there are back-to-back (B2B) type consistency points (CPs) found occurring on the loot aggregate.
In this scenario, how will performance of the client operations on the data aggregates be affected?
- A. During B2B processing, clients will be unable to write data.
- B. During B2B processing, all I/O to the node is stopped.
- C. Data aggregates will not be affected by B2B processing on another aggregate.
- D. During B2B processing, clients will be unable to read data.
Answer: C
Explanation:
A B2B type consistency point (CP) occurs when a new CP is triggered before the previous CP is completed, due to the second memory buffer reaching a watermark. This can cause write latency to increase as user write operations are not replied until a write buffer frees up. However, this only affects the aggregate that is undergoing the B2B processing, and not the other aggregates on the same node. Therefore, the performance of the client operations on the data aggregates will not be affected by B2B processing on the root aggregate. Reference = What is the Back-to-Back (B2B) Consistency Point Scenario?, What are the different Consistency Point types and how are they measured in ONTAP 9?, What are the different Consistency Point types and how are they measured?
NEW QUESTION # 37
Your customer is running a NetApp AFF A800 system with NetAppONTAP 9.8 software and states that their
NS224 shelf is not showing with the correct shelf ID. You analyze the data and the shelf shows an
identification of "1.SHFHUXXXXXXXXXX."
What is the cause of the reported Issue?
- A. A new shelf was added to the controller.
- B. The shelf has been power cycled.
- C. The shelf had a disk replaced too quickly.
- D. The shelf was cabled Incorrectly.
Answer: A
NEW QUESTION # 38
You have a NetApp ONTAP cluster consisting of four NetApp FAS8200 controllers with two NetApp
CN1610 cluster switches running ONIAP 9.8 software. You are receiving several alert messages stating that
the cluster network has degraded. After troubleshooting, you determine that the errors are being generated
fromNode 2, interface e0b.
In this scenario, what should you do first to solve this problem?
- A. Replace the Twinax cable between Node 2, Interface e0b. and the NetApp CN1610 switch.
- B. Replace both NetApp CN1610 switches.
- C. Replace the motherboard on Node 2.
- D. Replace the NetApp CN1610 switch that connects to Node 2, interface e0b.
Answer: C
NEW QUESTION # 39
You are trying to deploy a Connector in the AWS cloud from NetApp Cloud Manager. The deployment fails and shows the message 'Insufficient permissions to deploy Cloud Connector". You have verified the AWS access key and the AWS secret key.
In this scenario, what Is the reason that the deployment failed?
- A. The Connector can be deployed only in AWS GovCloud (US).
- B. No AWS Marketplace subscription is associated with Cloud Manager.
- C. The user lacks the permission to deploy within Cloud Manager.
- D. The required Identity and Access Management (IAM) policies were not Installed.
Answer: D
Explanation:
= The Connector is a software component that enables Cloud Manager to manage resources and processes within your AWS environment. To deploy a Connector in AWS, you need to have the correct IAM policies attached to your user account or role. These policies grant the Connector the permissions to perform various actions on your behalf, such as creating and deleting EC2 instances, VPCs, security groups, and so on. If you do not have the required IAM policies, the deployment will fail with the message 'Insufficient permissions to deploy Cloud Connector'. You can find the list of required IAM policies in the Connector deployment policy for AWS. Reference = Creating a Connector in AWS from Cloud Manager, page 3-4.
NEW QUESTION # 40
......
Achieve Success in Actual NS0-593 Exam NS0-593 Exam Dumps: https://www.testbraindump.com/NS0-593-exam-prep.html
Updated Network Appliance Study Guide NS0-593 Dumps Questions: https://drive.google.com/open?id=1iovz3EvbTwEsdznTf4M0-fmR23GJsBGU
